The idea: read the database's own log
A service writes to its database, and other systems need to know what changed. Instead of asking the service to publish events, or polling tables for new rows, change data capture (CDC) reads the log the database already keeps for crash recovery and replication. Every committed change is in that log, in commit order. A connector turns it into a stream of events.
The page has four parts: the Order service and its database orders_db, the database's write-ahead log, a Debezium-style connector running in Kafka Connect, and Kafka. Press Run Txn a few times (pick the change), then Run Connector, or run a demo. The connector select makes the next round crash or stop.
The WAL and LSNs
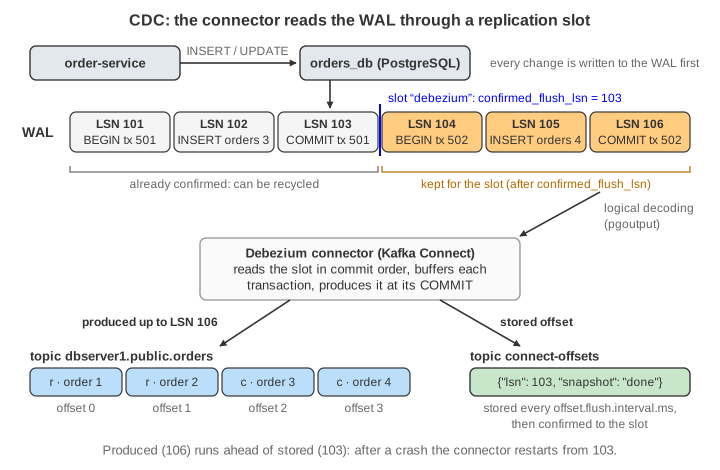
PostgreSQL writes every change to the write-ahead log (WAL) before it changes the table pages: BEGIN, then one record per inserted, updated or deleted row, then COMMIT or ABORT. Each record has a log sequence number (LSN), its position in the log, so LSNs only grow. (In MySQL the same role is played by the binlog and its file + position or GTID.) See WAL and Crash Recovery for why the log exists at all.
Replication slots and logical decoding
The connector connects like a replica does (see Primary–Replica Replication), but asks for logical decoding: instead of raw page changes, the pgoutput plugin hands it rows: "table orders, insert, id 3, status NEW". It reads through a replication slot, a named bookmark on the server. The slot remembers confirmed_flush_lsn, the last LSN the connector has confirmed. Changes arrive transaction by transaction, in commit order. The connector buffers each transaction and only emits it at its COMMIT. A rolled-back transaction emits nothing (Demo 2: a rolled-back transaction emits nothing).
Change events
Each change becomes one Kafka record, keyed by the row's primary key so all changes of one row stay in order in one partition. The value has:
| field | meaning |
|---|---|
op | r snapshot read, c create, u update, d delete |
before | the row before the change (updates and deletes; full only with REPLICA IDENTITY FULL) |
after | the row after the change (reads, creates and updates) |
source | database, table, transaction id, LSN, commit time |
A delete is followed by a tombstone (same key, empty value), so log compaction can drop the key. The page leaves the tombstone out.
The snapshot
The WAL only holds recent changes, not the rows that existed long before. So on its first start the connector takes a snapshot: it reads every row in a transaction that sees the database as of the slot's starting LSN, emits each as op = r, and then streams from that LSN. Nothing is missed and nothing is read twice (Demo 1: snapshot, then insert, update, delete).
Offsets and duplicates
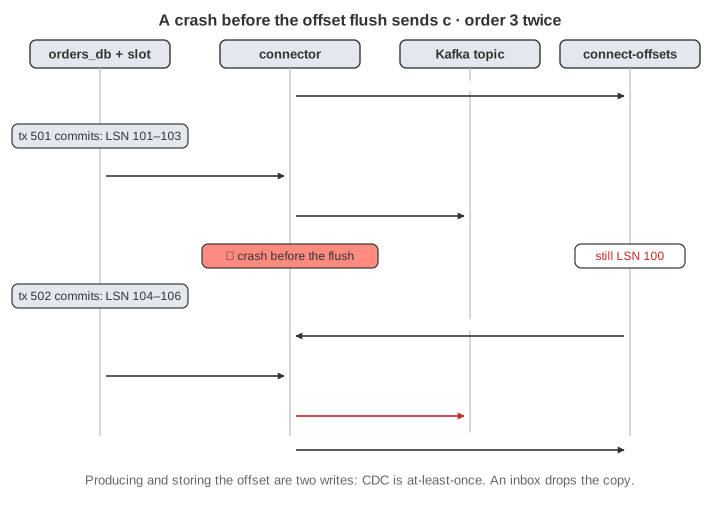
The connector's progress is its source offset, the last LSN it handled. Kafka Connect stores it in the connect-offsets topic every offset.flush.interval.ms, and the connector then confirms that LSN to the slot. Producing events and storing the offset are two separate writes. A crash between them restarts from the old offset, so the same changes are produced again (Demo 4: crash before the offset flush). CDC is at-least-once, like the polling relay. Each event carries its source LSN, so a consumer can drop a copy with an inbox table, see Transactional Outbox and Inbox.
WAL retention: the stuck slot
A slot keeps every WAL record after its confirmed_flush_lsn, so a connector that is down misses nothing. The flip side: while the connector is stopped, PostgreSQL cannot recycle that WAL, and the disk fills up (Demo 5: connector stopped). A forgotten slot is a classic way to fill a database server's disk. Watch pg_replication_slots, cap the damage with max_slot_wal_keep_size, and drop slots that are no longer used. On a quiet database whose WAL is driven by other databases, Debezium's heartbeats keep the slot moving.
The outbox event router
Raw table changes expose a service's internal schema to every consumer. The outbox pattern fixes that: the service writes a domain event (OrderPlaced, OrderPaid) to an outbox table in the same transaction as the business change. The connector captures only that table (table.include.list = public.outbox) and the outbox event router sends each insert to outbox.event.<aggregate type>, keyed by the aggregate id (Demo 3: outbox event router). Since the connector reads the log and not the table, the service can delete outbox rows right after inserting them.
CDC vs a polling relay
| polling the table | log tailing (CDC) | |
|---|---|---|
| load on the database | a query every interval | streams the log; no queries |
| latency | up to one poll interval | close to the commit |
| deletes | invisible (the row is gone) | seen, with the old row |
| order | by id or timestamp, which can differ from commit order | commit order |
| intermediate states | missed if a row changes twice between polls | every change |
| delivery | at-least-once | at-least-once |
| operations | just SQL | logical replication, a slot to watch, Kafka Connect |
See also How Kafka Moves a Message for the topic, partitions and offsets on the receiving side.
For what happens inside PostgreSQL before the connector sees a change (reorder buffer, restart_lsn vs confirmed_flush_lsn, max_slot_wal_keep_size), see PostgreSQL Logical Decoding.
What the page leaves out
Several tables and partitions, schemas and the schema registry, tombstones, large transactions that span many rounds, incremental snapshots (signals), heartbeats, publications, MySQL binlog/GTID details, Kafka Connect's exactly-once source support (KIP-618), and failover of the slot to a new primary.