The idea: know who is alive without a central server
A cluster of a few to a few thousand machines needs a membership list: who is in the cluster, and who has died. A central server that pings everyone is a bottleneck and a single point of failure, and having everyone ping everyone costs N² messages. Gossip protocols spread news the way a rumor spreads: each member tells a few random others, who tell a few more. SWIM (Scalable Weakly-consistent Infection-style Membership, Das, Gupta and Motivala, 2002) builds failure detection on top: each member checks one random member per period, and news about failures rides on those checks.
| On the page | Meaning |
|---|---|
| circles N1 to N9 | what is really true: grey-blue alive, yellow has the rumor, grey ✗ crashed, purple frozen in a GC pause, faded N9 not a member yet; inc is the member's own incarnation number |
| membership views | row N3 is what N3 believes about every member: A0 alive with incarnation 0, S0·2 suspect with 2 periods left, D0 dead; the diagonal is the member itself |
| piggyback column | the updates a member still has to pass on, with the sends left: N5?×3 |
| message boxes | ping, ack, ping-req, followed by the updates they carry: N5? suspect, N5✓ alive, N5✗ dead, N9+ joined |
| gossip chart | how many members have the rumor after each round |
Push gossip and log N rounds
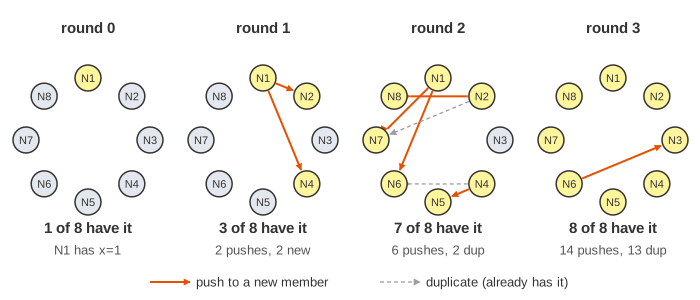
In push gossip a member with a new update sends it to fanout peers picked at random (2 here; memberlist's GossipNodes is 3). Every member that receives it does the same in the next round. While few members have it, almost every push reaches someone new, so the number of informed members multiplies each round; N members are covered in about log N rounds (8 members: about 3), and the protocol tolerates lost messages and crashed members without any coordination (Demo 1).
The price is duplicates: near the end most pushes go to members that already have the update, and the senders cannot know that. Each member therefore pushes for a limited number of rounds (3 here) and then stops. A member can still be missed by bad luck, so real systems add a slower anti-entropy sync that compares full state now and then (memberlist's push-pull every 30 seconds; see Merkle Trees and Anti-Entropy).
SWIM: ping, ack and ping-req
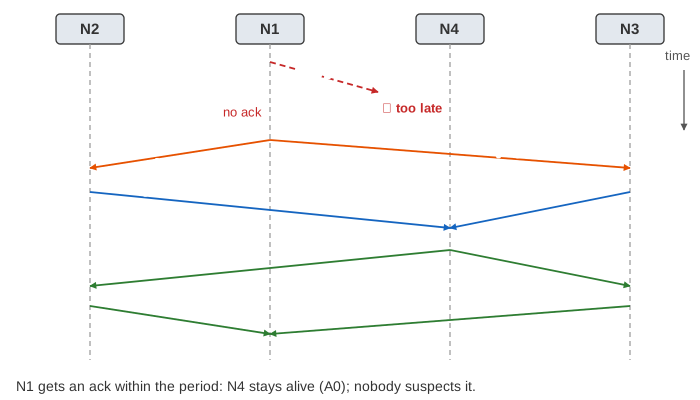
SWIM divides time into protocol periods (memberlist's ProbeInterval, 1 second). In each period every member picks one member and sends it a ping; the target answers ack. Each member sends one ping per period, so the load stays constant however large the cluster is. The page picks targets with one random shift per period, so every member is also pinged exactly once.
A missing ack does not prove much: the target may be fine and only the path between the two members slow or lossy. So the prober sends ping-req to k other members (k = 2 here; IndirectChecks = 3), and each of them pings the target and forwards the ack. Only if none of these paths gets an ack before the period ends does the prober suspect the target (Demo 3: a slow link between N1 and N4 alone does not get N4 suspected).
Suspect, dead and incarnation numbers
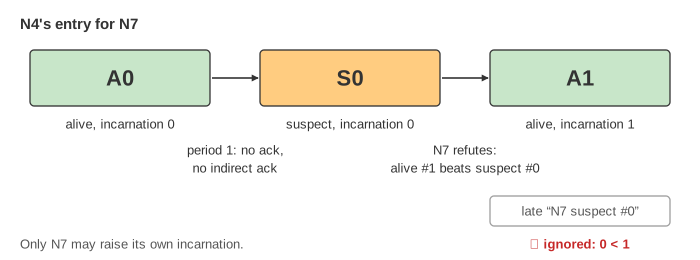
The original SWIM paper declared a member dead as soon as the indirect probe failed. A member that is only slow for a moment (a long garbage-collection pause, a full network buffer) was then thrown out. The improved version marks it suspect first and starts a suspicion timeout (3 periods here; memberlist uses SuspicionMult · log N periods). If nobody refutes the suspicion in time, it becomes dead, and that is final for this incarnation (Demo 2).
Each member owns an incarnation number that only it may raise. When a member hears that it is suspected, it increments its incarnation and spreads alive with the new number. The rules decide which news wins: newer incarnation beats older, and at the same incarnation suspect beats alive and dead beats both (Demo 4: N7 is suspected during a GC pause and refutes it with incarnation 1).
| A member receives | It replaces the entry when |
|---|---|
| alive, incarnation i | the entry has an incarnation lower than i |
| suspect, incarnation i | alive with incarnation ≤ i, or suspect with incarnation < i |
| dead, incarnation i | alive or suspect with incarnation ≤ i |
| suspect or dead about itself | never; it refutes: incarnation = i + 1 and it spreads alive |
Piggybacking membership changes
SWIM sends no separate messages for news. Every member keeps a small buffer of recent updates (N5 suspect, N7 alive #1, N9 joined) and attaches a few of them to every ping and ack it sends anyway. Each update is sent about λ·log N times (4 here; memberlist's RetransmitMult · log(N+1)) and then dropped. Since pings go to random members, the news spreads exactly like gossip, in O(log N) periods, at zero extra message cost. Watch the piggyback column: counts go down with each send, and a member that learns something new adds it to its own buffer.
Joining
A new node needs the address of one member, the seed. It sends a join to the seed, the seed answers with its full membership list and starts piggybacking N9+; the rest of the cluster learns about the new member over the next few periods (Demo 5). Leaving works the same way with a "left" update, so the member is not mistaken for a failure.
Where it is used
HashiCorp memberlist (behind Consul and Serf, and Nomad) is SWIM with the suspicion and incarnation rules shown here plus Lifeguard, which lengthens timeouts on a member that sees itself missing acks. Cassandra and ScyllaDB gossip node state once a second with three random peers. Redis Cluster nodes ping each other on the cluster bus and mark a master PFAIL, then FAIL when a majority agrees, which is the same suspect-then-confirm idea. Gossip spreads membership, but it does not give agreement: for one leader or one log order, see Raft and Leader Election.
See also Consistent Hashing (what a membership list is used for), CRDTs (data that merges cleanly however gossip delivers it), Lamport and Vector Clocks and The CAP Theorem.
What the page leaves out
Real members ping a target from their own shuffled list, round-robin, so a member can be pinged several times in one period; the page uses one shift for everybody so every member is pinged once. Messages are UDP packets with a timeout inside the period, and the indirect ping has its own shorter timeout; the page counts a slow link as simply lost. Only pings and acks carry updates here (real SWIM piggybacks on ping-req too), at most 2 per message. Lifeguard's dynamic timeouts and the "suspicion confirmations" that shorten a timeout, the periodic push-pull full-state sync, graceful leave, TCP fallback pings, encryption and the network-coordinate (Vivaldi) data that memberlist also gossips are left out. Each member's suspicion timer is counted in whole periods, and a member's own timers stop while it is crashed or paused.