The idea: cluster metadata is a log too
A Kafka cluster has to agree on its metadata: which brokers are alive, which topics exist, and for every partition its replicas, its leader and its in-sync replicas (ISR). Older Kafka kept this in ZooKeeper, a separate system. Since KIP-500, Kafka keeps it itself, in KRaft mode (Kafka Raft): the metadata is an ordinary Kafka log, the internal topic __cluster_metadata with one partition, and every change is a record appended to it.
A few nodes, the controllers (listed in controller.quorum.voters, usually 3 or 5), replicate that log with the Raft consensus protocol (KIP-595). Their Raft leader is the active controller: it is the only node that decides and writes. The other controllers are hot standbys with a full copy. Brokers read the same log and keep the result in their metadata cache.
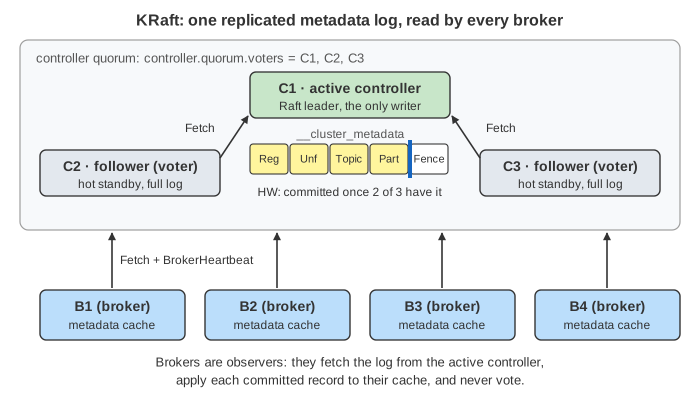
The page runs 3 controllers C1, C2, C3 and 4 brokers. B1, B2 and B3 are registered when it starts; B4 is a spare you can start. Topics orders (3 partitions) and users (2 partitions) have replication factor 2. Times are scaled down, and each action runs until every record it wrote is committed and applied.
Records in __cluster_metadata
Each cell on the canvas is one record, with a short name:
| On the canvas | Record | Written when |
|---|---|---|
| Register B4 | RegisterBrokerRecord | a broker starts and registers; it is fenced at first |
| Unfence B4 | BrokerRegistrationChangeRecord (fenced = false) | the broker has caught up with the log |
| Fence B2 | FenceBrokerRecord | a broker missed its heartbeats |
| Topic orders | TopicRecord | a topic is created (name and topic id) |
| Part orders-0 | PartitionRecord | a partition is created: replicas, leader, ISR |
| PartChg orders-1 | PartitionChangeRecord | a partition's leader or ISR changes |
| Leader C2 e2 | LeaderChangeMessage (a control record) | a controller becomes leader of a new epoch |
A record holds only the change, not the whole state. The state is what you get by applying all records in order, the way a database rebuilds its tables from its write-ahead log. Newer metadata versions write BrokerRegistrationChangeRecord for fencing too, and there are more record types: configs, quotas, ACLs, producer ids and feature levels.
Committing a record
The active controller handles every request that changes metadata. Demo: create topic orders follows one change from start to end:
- The admin client sends
CreateTopics. The active controller picks replicas for each partition and appends aTopicRecordand onePartitionRecordper partition to its log. The new cells are white: not committed yet. - The followers already have a
Fetchwaiting at the leader (a long poll), and it returns with the new records. KRaft followers pull, like Kafka replicas, instead of having the leader pushAppendEntriesas in plain Raft. - A follower's next
Fetch(offset n)means "I have everything before n". Once a majority of the voters (2 of 3) has a record, the leader moves the high watermark (HW, the blue bar) past it: the record is committed and gets its epoch colour. - The next fetch answers carry the HW to the followers, and the committed records to the brokers. Each broker applies them to its cache. Only then does the controller answer the admin client.
One controller may be down and nothing stops, because 2 of 3 is still a majority (Demo: a follower controller is down). When the controller comes back, it fetches the records it missed from where its own log ends.
Brokers: heartbeats and fencing
Brokers are observers of the quorum. They fetch the log from the active controller like a follower does, but they do not vote and do not count toward the majority. Every broker.heartbeat.interval.ms (2 s) a broker also sends a BrokerHeartbeat to the active controller, with how far it has applied the log.
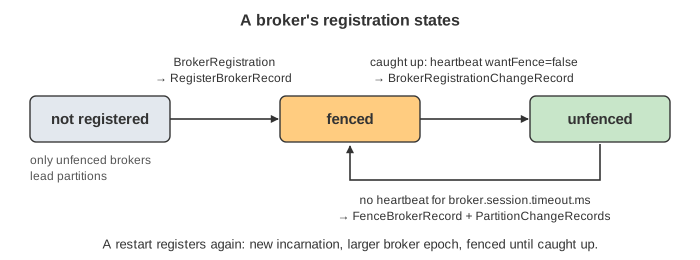
If a broker sends no heartbeat for broker.session.timeout.ms (9 s), the active controller fences it. In the same batch it writes a PartitionChangeRecord for each partition that had the broker in its ISR. A partition that the broker led gets a new leader from the rest of its ISR, and its leader epoch goes up by one, so the old leader can no longer be followed by mistake. In Demo: broker dies, is fenced, leaders move, B2 dies, orders-1 moves to B3 with leader epoch 1, and orders-0 keeps B1 as leader with a smaller ISR.
A starting broker sends BrokerRegistration. The controller writes a RegisterBrokerRecord, and the broker's broker epoch is that record's offset, so a newer start always has a larger epoch and old requests from a zombie can be rejected. The broker starts fenced: it gets no leadership until its heartbeat shows it has applied the log past its own registration. Then the controller unfences it (Demo: new broker B4 joins). A broker coming back after a crash still has its local copy of the log and fetches only what it missed. Its partition leaders then add it back to the ISR with AlterPartition (Demo: fenced broker comes back). Leadership does not move back by itself; the preferred-leader election (auto.leader.rebalance.enable) does that later.
When the active controller fails
In Demo: active controller fails, new election, C1 crashes. The followers get no fetch answer for controller.quorum.fetch.timeout.ms; after a random part of controller.quorum.election.timeout.ms, C2 becomes a candidate with epoch 2 and asks C3 for its vote. C3 grants it, because C2's log is at least as up to date as its own. With 2 of 3 votes C2 is leader. It sends BeginQuorumEpoch and appends a LeaderChange control record: a Raft leader can only commit once a record of its own epoch is on a majority. Brokers whose fetches to C1 fail ask another voter; every answer names the current leader and epoch, so they find C2. The next topic, users, is written in epoch 2 (blue cells).
The new active controller is ready at once, because it already has the whole metadata log in memory. With ZooKeeper, a new controller first had to read every topic and partition from ZooKeeper, which took minutes on big clusters. That failover time is one of the main reasons for KRaft. The Raft page shows the election itself in detail: split votes, terms, the up-to-date check and log repair.
Snapshots
The log would grow forever, so every node, controller or broker, writes a snapshot of the state from time to time. That happens after metadata.log.max.record.bytes.between.snapshots (20 MB) of new records, or after metadata.log.max.snapshot.interval.ms (1 hour). On the page you press Take Snapshot instead. A snapshot holds the state, one record per broker, topic and partition, and is named by its end offset and epoch. The records before it can be deleted.
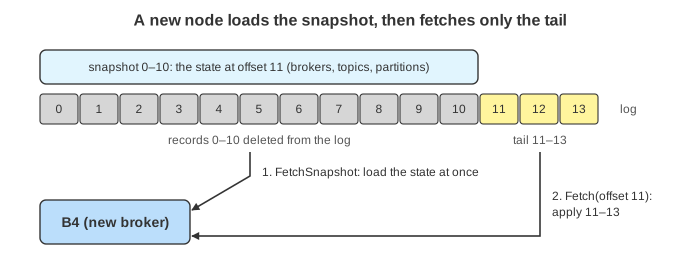
A node that asks for an offset that is already deleted is told to load the snapshot instead (FetchSnapshot), and then it fetches the tail (Demo: snapshot, then B4 loads it). Compare Demo: new broker B4 joins, where B4 replays the log from offset 0.
KRaft vs ZooKeeper
| ZooKeeper mode | KRaft mode | |
|---|---|---|
| Where metadata lives | znodes in a separate ZooKeeper ensemble | the __cluster_metadata log in Kafka itself |
| Controller | one broker, elected through ZooKeeper | Raft leader of a controller quorum |
| Controller failover | the new controller reloads all metadata from ZooKeeper | the new leader already has the log in memory |
| Brokers learn changes | the controller pushes UpdateMetadata / LeaderAndIsr requests | brokers fetch the log and apply it in order |
| Liveness | ZooKeeper session of each broker | BrokerHeartbeat and fencing |
| Versions | removed in Kafka 4.0 | production-ready since 3.3, the only mode since 4.0 |
Because every broker applies the same records in the same order, two brokers that have reached the same offset have exactly the same metadata. The offset says how fresh a broker's view is, which is how the controller knows that a starting broker has caught up.
See also How Kafka Moves a Message and Kafka Consumer Groups, and the other Kafka internals pages: log segments, log compaction, replication, HW and ISR and zero-copy reads. For the consensus underneath, see Raft and Paxos; for other ways to pick a leader, see Leader Election; and for replicated databases, see Database Replication.
What the page leaves out
Most record types (configs, ACLs, quotas, producer ids, feature levels, and NoOpRecord heartbeats from the leader), batching of several records in one Raft batch, log divergence and truncation when an old leader comes back with uncommitted records, pre-vote and randomized election timeouts (the page always picks the next controller), dynamic quorum membership (KIP-853), combined mode (a node that is both broker and controller), controlled shutdown, the ZooKeeper migration path, and the partition data itself: the page shows only metadata.