The idea: a packet climbs from the NIC to recv()
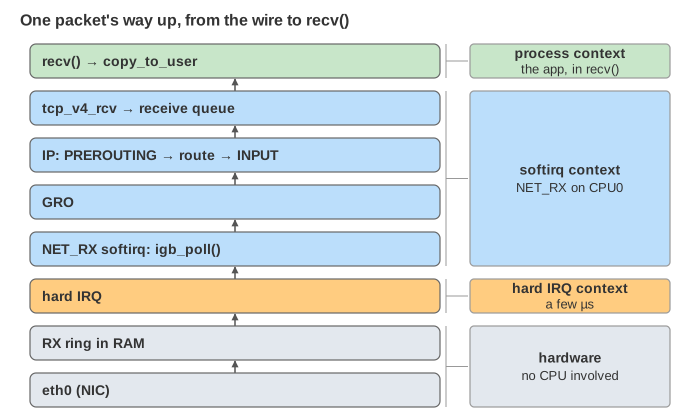
A program that calls recv() on a TCP socket just gets bytes. Behind that call, every packet climbs through three worlds. The hardware (the network card and its ring of buffers in RAM) takes the frame off the wire without the CPU. The kernel handles it in an interrupt and a softirq: IP, the firewall hooks, TCP. Only at the end does user space see it, when recv() copies it into the program's buffer.
The page follows one server (10.0.0.5, one CPU core, a NIC eth0) and one process, app, blocked in recv() on an open TCP connection from 10.0.0.9. Pick a packet and press Send Packet, or run a demo. Sizes are scaled down so they fit on the canvas: the RX ring has 4 descriptors and the receive buffer holds 8 segments of 1000 B.
The RX ring and DMA
At start-up the driver fills a ring of descriptors in RAM, each pointing at an empty buffer. When a frame arrives, the NIC checks its checksum and MAC address, writes it by DMA straight into the next free buffer and marks the descriptor done. The CPU is not involved. The ring size is a driver setting: ethtool -g eth0 shows it (often 256 to 4096), ethtool -G eth0 rx 4096 changes it. Direct Memory Access (DMA): How a Network Card Moves Packets shows the descriptors, head and tail pointers in detail.
If the CPU doesn't empty the ring fast enough, the NIC finds no free buffer and drops the frame. It never reaches the kernel, so only the NIC's counters see it: rx_missed_errors in ethtool -S eth0, missed in ip -s link. TCP recovers by retransmitting, but slowly (Demo: RX ring full).
Hard IRQ, NAPI and the softirq budget
The NIC then raises an interrupt. The hard IRQ handler runs with other interrupts blocked, so it does as little as possible: it masks the NIC's interrupt and calls napi_schedule(), which puts the device on this CPU's poll list and raises the NET_RX softirq. That is the top half. See Kinds of Interrupts in Linux for how the CPU gets there.
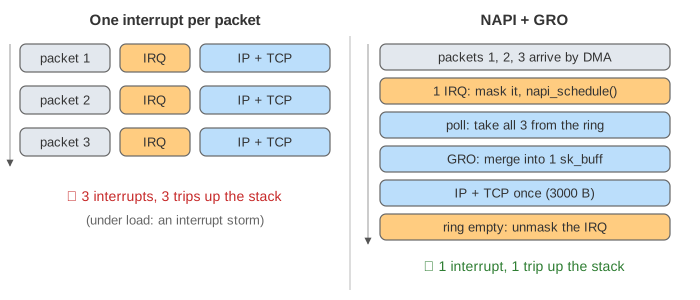
The softirq (the bottom half) runs net_rx_action(), which calls the driver's poll function. It takes packets off the ring, wraps each in an sk_buff and refills the descriptor with a fresh buffer. It may process up to net.core.netdev_budget = 300 packets per round (and at most netdev_budget_usecs = 2000 µs; each device gets a weight of 64 per turn). When the ring is empty it calls napi_complete_done() and unmasks the interrupt. Under load the ring never empties, interrupts stay off and the kernel just polls: many packets cost one interrupt (Demo: three packets, one interrupt). When the budget runs out with work left, the rest goes to the ksoftirqd thread and /proc/net/softnet_stat counts a time_squeeze.
GRO: merge before climbing
Generic Receive Offload (napi_gro_receive()) looks at the packets of one poll round. Consecutive TCP segments of the same connection are merged into one big sk_buff, up to 64 KB. IP, netfilter and TCP then run once for the whole batch instead of once per packet. ethtool -k eth0 shows generic-receive-offload: on.
netfilter: PREROUTING and INPUT
ip_rcv() checks the IP header and runs the PREROUTING hook, where conntrack and destination NAT happen (see NAT). Then the routing lookup decides: is the destination one of this host's addresses (deliver locally) or must the packet be forwarded? A local packet passes the INPUT hook, where the usual firewall rules sit. A forwarded one takes the FORWARD and POSTROUTING hooks instead.
| Hook | When | Typical use |
|---|---|---|
PREROUTING | every incoming packet, before routing | DNAT, port forwarding, conntrack |
INPUT | packets for this host | firewall: which ports are open |
FORWARD | packets routed through this host | router and container firewalls |
OUTPUT | packets this host sends | outgoing filters |
POSTROUTING | every outgoing packet, after routing | SNAT, masquerade |
A -j DROP rule frees the sk_buff silently: the sender gets no answer and retransmits until it gives up. Its only trace is the rule's pkts counter in iptables -L INPUT -v (Demo: iptables DROP on INPUT). -j REJECT would send back a RST or an ICMP error instead.
TCP: the socket, the window, the wake-up
tcp_v4_rcv() finds the socket by the 4-tuple (source and destination address and port). If there is no connected socket and no listening socket on that port, TCP answers with a RST and the client's connect() fails with ECONNREFUSED (Demo: nobody listening). How a listening socket turns SYNs into connections is on The Linux Listen Backlog.
For a connected socket, TCP checks the sequence numbers and appends the data to the socket's receive queue. The queue is limited by the receive buffer (SO_RCVBUF, auto-tuned between the values in net.ipv4.tcp_rmem, by default 4096, 131072 and 6291456 bytes). TCP sends an ACK that carries the window: how much free room is left. Then sk_data_ready() wakes the task sleeping on the socket's wait queue. select, poll and epoll are woken by the same call.
When the program doesn't read, the queue fills and the window shrinks to 0. The sender must stop; it sends a small window probe now and then. As soon as the program reads, TCP sends a window update and the data flows again (Demo: receive buffer full). ss -tm shows the buffer use per socket; TcpExtTCPToZeroWindowAdv counts the zero windows sent.
recv(): the copy to user space
recv() is a system call (see A Linux System Call, Step by Step). tcp_recvmsg() copies bytes from the receive queue into the program's buffer with copy_to_user() and frees the sk_buffs. This is the packet's second copy: the first was the NIC's DMA. If the queue is empty, recv() sleeps on the socket's wait queue until sk_data_ready() wakes it. The socket API itself is on A TCP Socket in Linux.
Where buf lives
The buf that recv() gets is just a virtual address in the process, here 0x7ffd2a40c000, an array on main()'s stack. Every process has its own virtual address space (code, heap, shared libraries, stack); the MMU turns each address into a physical one by looking it up in the process's page table (cached in the TLB). The MEMORY band at the bottom of the canvas shows that lookup: the page of buf maps to physical frame 0x3c1f2.
So both copies of the packet end up in the same RAM. The NIC's DMA writes the frame into the RX buffers (frames 0x1a200–0x1a203, which the ring's descriptors point to by physical address). copy_to_user() then runs on the CPU, in the process's context: it reads the packet through the kernel's direct map (all of RAM mapped at 0xffff888000000000 and up) and writes through the user address of buf, which the MMU sends to frame 0x3c1f2. If buf were a freshly malloc()ed page that had never been touched, it would have no frame yet: the first write would page-fault, and the kernel would allocate a frame and continue the copy (see Virtual Memory). A bad pointer makes recv() fail with EFAULT instead of crashing the kernel.
Where packets get dropped
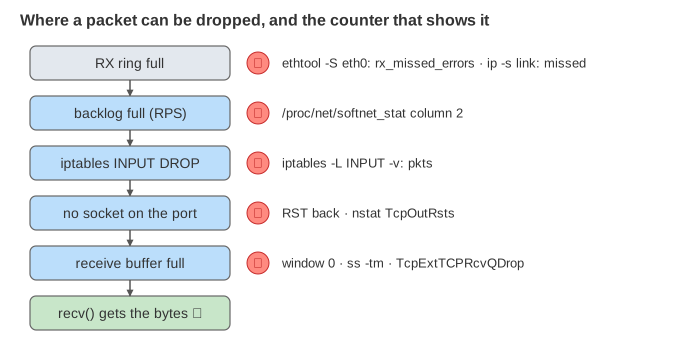
Each place a packet can die has its own counter, so the first question when "packets are lost" is which counter grows.
| Where | Counter / command | Usual fix |
|---|---|---|
| RX ring full | ethtool -S eth0 rx_missed_errors, ip -s link missed | bigger ring (ethtool -G), more queues and CPUs (RSS) |
| per-CPU backlog full (RPS) | /proc/net/softnet_stat column 2 | raise net.core.netdev_max_backlog (1000) |
| softirq out of budget | softnet_stat column 3 (time_squeeze) | raise netdev_budget |
| firewall | iptables -L -v / nft list ruleset | fix the rule |
| no socket on the port | nstat TcpOutRsts, RST in tcpdump | start the service, check the port |
| receive buffer full | ss -tm, TcpExtTCPRcvQDrop, zero windows | read faster, bigger tcp_rmem |
The send path, in short
Sending runs the same layers the other way. send() copies the data into the socket's send queue and returns. TCP builds segments (tcp_write_xmit()), IP routes them and runs the OUTPUT and POSTROUTING hooks, dev_queue_xmit() puts them in the device's qdisc (fq_codel by default), and the driver writes a descriptor into the TX ring. The NIC reads the frame by DMA and sends it, then raises an interrupt so the driver can free the buffer. TCP keeps its copy until the ACK arrives (Demo: the send path, in short).
Traffic to 127.0.0.1 makes this whole climb too, through the lo device and the NET_RX softirq; a unix socket skips it. See Unix Socket vs TCP on Loopback.
What the page leaves out
The page has one CPU and one RX queue. Real NICs have many queues spread over CPUs (RSS), and the kernel can spread packets further in software (RPS, RFS); that per-CPU backlog is where netdev_max_backlog applies. It also skips interrupt coalescing (ethtool -C), checksum and segmentation offloads, XDP and AF_XDP, busy polling, zero-copy receive, conntrack details, delayed ACKs, IPv6 and UDP. The ring and the receive buffer are scaled down; real segments are up to 1448 B (the MSS) and ACK numbers count bytes.