The idea: one lock table in shared memory
PostgreSQL runs one backend process per connection. The processes share one lock table in shared memory, managed by the lock manager (src/backend/storage/lmgr). Every lock a transaction holds or waits for is a row there, and the pg_locks view shows them: the object, the mode, the process and granted = t or f. A request that can't be granted joins the object's wait queue and the backend sleeps until someone releases a lock. Locks are kept until the transaction ends: COMMIT or ROLLBACK releases them all at once.
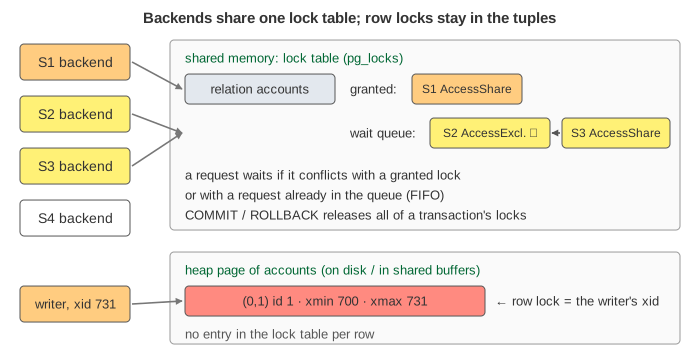
The canvas follows four sessions, S1 to S4, on one table accounts(id, bal) with two rows. Pick a session and a statement and press Execute; each statement moves the clock 0.1 s. Wait 1 s lets time pass so the timers can fire.
Eight table lock modes
Before a statement touches a table it locks the table itself, in one of eight modes. The weaker the mode, the more other statements can run at the same time.
Mode (as in pg_locks) | Taken by | Conflicts with |
|---|---|---|
| AccessShareLock (AS) | SELECT | AX only |
| RowShareLock (RS) | SELECT … FOR UPDATE / FOR SHARE | X, AX |
| RowExclusiveLock (RX) | INSERT, UPDATE, DELETE, MERGE | S, SRX, X, AX |
| ShareUpdateExclusiveLock (SUX) | VACUUM, ANALYZE, CREATE INDEX CONCURRENTLY | SUX, S, SRX, X, AX |
| ShareLock (S) | CREATE INDEX | RX, SUX, SRX, X, AX |
| ShareRowExclusiveLock (SRX) | CREATE TRIGGER, some ALTER TABLE | RX, SUX, S, SRX, X, AX |
| ExclusiveLock (X) | REFRESH MATERIALIZED VIEW CONCURRENTLY, LOCK TABLE … IN EXCLUSIVE MODE | all but AS |
| AccessExclusiveLock (AX) | most ALTER TABLE, DROP, TRUNCATE, VACUUM FULL, plain LOCK TABLE | everything, even SELECT |
The names are historical and confusing: RowExclusiveLock is a table lock, and none of these modes locks a row. The rule to remember: reads and writes (AS, RS, RX) never block each other; DDL blocks them. Only AccessExclusiveLock blocks a plain SELECT. Demo: lock modes and the matrix runs a SELECT and an UPDATE side by side (AS and RX are compatible), then a CREATE INDEX that must wait for the UPDATE (S conflicts with RX).
The conflict matrix
Whether a request can be granted is a lookup in a fixed table (LockConflicts in lock.c): the requested mode against every mode another transaction holds on the same object. Locks of the same transaction never conflict with each other. The canvas colours the cells it checks: green ✓ compatible, red ✗ conflict.
| requested ↓ / held → | AS | RS | RX | SUX | S | SRX | X | AX |
|---|---|---|---|---|---|---|---|---|
| AS | ✗ | |||||||
| RS | ✗ | ✗ | ||||||
| RX | ✗ | ✗ | ✗ | ✗ | ||||
| SUX | ✗ | ✗ | ✗ | ✗ | ✗ | |||
| S | ✗ | ✗ | ✗ | ✗ | ✗ | |||
| SRX | ✗ | ✗ | ✗ | ✗ | ✗ | ✗ | ||
| X | ✗ | ✗ | ✗ | ✗ | ✗ | ✗ | ✗ | |
| AX | ✗ | ✗ | ✗ | ✗ | ✗ | ✗ | ✗ | ✗ |
Note that S does not conflict with S (two CREATE INDEX can run together) but SUX conflicts with itself (only one VACUUM per table).
The wait queue and the ALTER TABLE pile-up
A request is granted only if it conflicts with no lock granted to another transaction and with no request already waiting in the queue. The second rule keeps the queue fair: without it, a steady stream of SELECTs would starve an ALTER TABLE forever. The price is the most common lock outage in production. A long SELECT holds AccessShareLock; an ALTER TABLE arrives and queues for AccessExclusiveLock; now every new SELECT, which would be compatible with the first one, queues behind the ALTER. The table is unreadable until the long SELECT ends (Demo: ALTER TABLE queue pile-up).
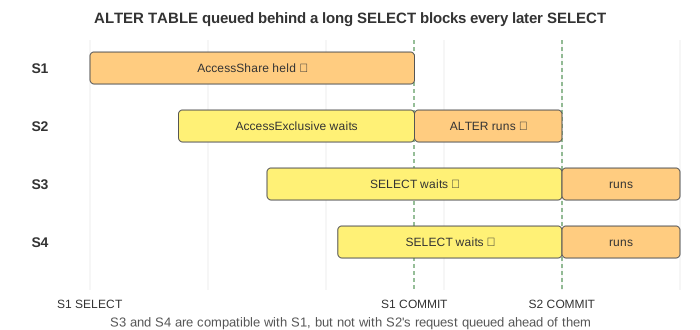
The fix is to run DDL with a short lock_timeout: SET lock_timeout = '2s' makes the ALTER give up with ERROR: canceling statement due to lock timeout instead of holding up the queue, and you retry it later (Demo: lock_timeout saves the queue). To find the culprit, pg_blocking_pids(pid) lists the processes a backend waits for, and pg_stat_activity.wait_event_type = 'Lock' lists the waiters.
Row locks live in xmax
A table can have billions of rows, so PostgreSQL does not put row locks in the lock table. An UPDATE, DELETE or SELECT … FOR UPDATE writes its own xid into the tuple's xmax (with flag bits that say which of the four row-lock strengths it is: FOR KEY SHARE, FOR SHARE, FOR NO KEY UPDATE, FOR UPDATE). The lock is on disk, in the heap page.
How does a second writer wait for it, then? Every transaction, once it has an xid, holds an ExclusiveLock on its own transactionid until it ends. A writer that finds a running xid in xmax:
- takes the heavyweight tuple lock for that row (so a third writer queues behind it, not in a free-for-all);
- asks for ShareLock on the holder's transactionid. It conflicts with the holder's ExclusiveLock, so it sleeps in that queue;
- when the holder commits or aborts, its transactionid lock goes away and the waiter wakes, drops the ShareLock, re-reads the row and writes its own xid into
xmax. Under READ COMMITTED, if the holder committed an UPDATE, it follows the update chain to the new version and applies its change there.
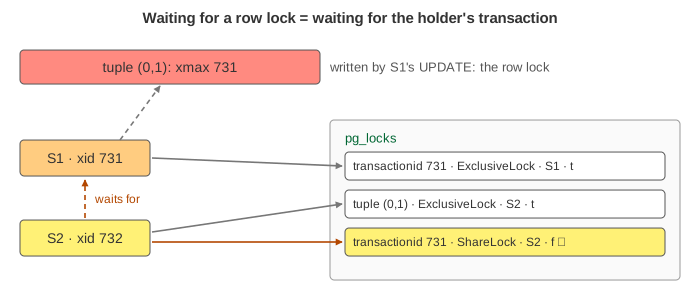
That is why pg_locks shows row waits as locktype = transactionid, and why read-only transactions, which never get an xid, never appear there with one (Demo: row lock in xmax). The xmax of a lock-only mark stays in the tuple after the locker ends; it is simply ignored once pg_xact says the xid is over.
deadlock_timeout and the deadlock detector
Checking for a deadlock on every wait would be costly, and most waits end quickly. So a backend that starts to wait just sets a timer and sleeps. Only if it is still waiting after deadlock_timeout (default 1 s) does it run DeadLockCheck: it locks every partition of the lock table, builds the wait-for graph (an edge from each waiter to each process holding or queued ahead with a conflicting mode) and searches for a cycle through itself. A cycle means the backend aborts its own transaction:
ERROR:  deadlock detected
DETAIL:  Process 4101 waits for ShareLock on transaction 732; blocked by process 4102.
Process 4102 waits for ShareLock on transaction 731; blocked by process 4101.
So the victim is whichever backend's timer fires first while the cycle exists, usually the one that started waiting first, not the youngest or cheapest transaction (Demo: deadlock after deadlock_timeout). The other one simply gets its lock when the victim's locks are released. If no cycle is found, the backend goes back to sleep and, with log_lock_waits = on, logs that it has waited longer than deadlock_timeout.
| PostgreSQL | MySQL / InnoDB | |
|---|---|---|
| Row locks | xid in the tuple's xmax; waiters queue on the transactionid lock | lock structs in memory, one bitmap per page |
| Table locks | 8 modes, taken by every statement | metadata locks (MDL) for DDL |
| Deadlock check | after deadlock_timeout (1 s), by the waiting backend | at once, on every wait |
| Victim | the backend that ran the check | the smaller transaction (fewest rows changed or locked) |
See also Two-Phase Locking and Deadlocks for InnoDB-style row locks and immediate detection, MVCC and Isolation Levels for what happens to a waiter under REPEATABLE READ (it fails with a serialization error instead of following the update chain), PostgreSQL Serializable Snapshot Isolation for the SIREAD locks that also appear in pg_locks, the PostgreSQL heap page for where xmax sits in a tuple header, the PostgreSQL process model for the backends that share the lock table, and How PostgreSQL Runs a Query for the bigger picture.
InnoDB has gap and next-key locks that PostgreSQL lacks; see InnoDB record, gap and next-key locks. MySQL has the same pile-up with metadata locks: see MySQL Metadata Locks and Online DDL.
What the page leaves out
Fast-path locks (weak relation locks are kept in a per-backend array, not the shared table, unless a strong lock exists), the 16 partitions of the lock table and lightweight locks (LWLocks) that protect it, virtualxid locks, advisory locks, SIREAD predicate locks, and locks on indexes, sequences and the catalog. The multixact used when several transactions share-lock one row, the four row-lock strengths beyond the two shown, and the queue rearrangement the detector does to break "soft" deadlocks without aborting anyone. Here a transaction starts with its first statement and every statement in a failed transaction errors until ROLLBACK, as in a real transaction block.