The idea: three ways to run the same instructions
Harris and Harris build three MIPS processors from the same parts: a program counter, an instruction memory, a register file, an ALU and a data memory. They differ only in how they use time:
- The single-cycle processor runs each instruction in one long clock cycle. The cycle must fit the slowest instruction,
lw. - The multicycle processor breaks each instruction into short steps, one per cycle (fetch, decode, execute, memory, write back). A
beqneeds 3 cycles, alw5. Only one instruction runs at a time. - The pipelined processor also has 5 steps, called stages (IF, ID, EX, MEM, WB), but starts a new instruction every cycle. Up to 5 instructions are in flight at once.
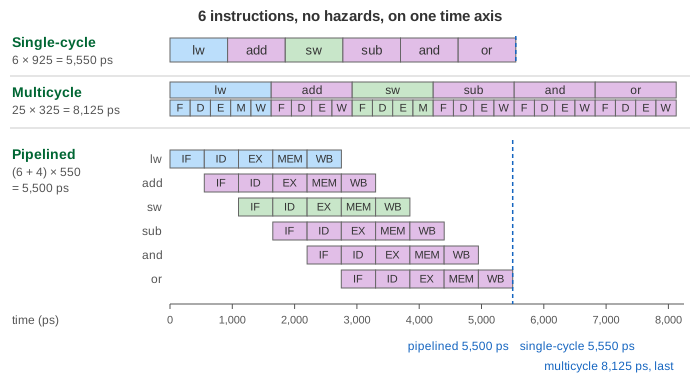
The page runs the same 10-instruction program on all three, in three lanes on one time axis in picoseconds. Each step moves the clock forward by one pipeline cycle (550 ps), or by a few cycles on long programs. A box is drawn when it starts, so the blue cursor shows what each processor is doing at that moment. When a processor finishes, its time goes to the scoreboard.
How to read the lanes. Single-cycle: one box per instruction, numbered by its line in the program listing. Multicycle: one box per instruction, and under it one box per clock cycle with its step letter (F D E M W). Pipelined: one row per stage; each cycle shows which instruction is in that stage. A grey box is a bubble (a stage doing nothing because of a stall or a flush), a red ✗ is a fetched instruction that was thrown away. The colours are the instruction types: blue lw, green sw, purple R-type, yellow beq.
Execution time = instructions × CPI × Tc
The time a program takes is the product of three numbers:
- N, the number of instructions executed (the same for all three here: same program, same instruction set);
- CPI, the average number of clock cycles per instruction;
- Tc, the clock period, set by the slowest path that must finish within one cycle (the critical path).
A design that lowers one number often raises another. The scoreboard shows the product for each processor, for example 10 × 1.60 × 550 ps = 8,800 ps for the pipeline in Demo 1.
Where each clock period comes from
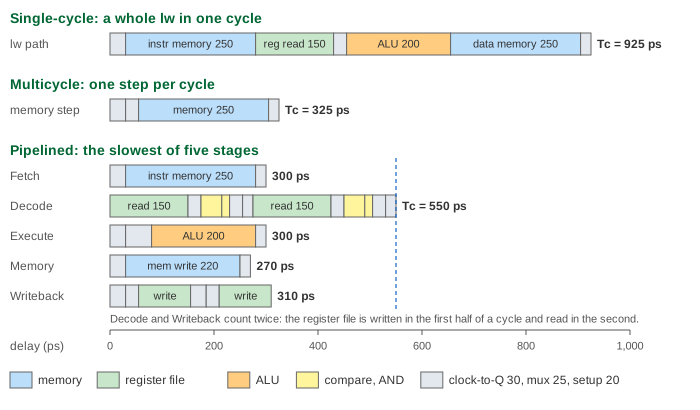
Harris uses these delays (Table 7.6): register clock-to-Q 30 ps, register setup 20 ps, multiplexer 25 ps, ALU 200 ps, memory read 250 ps, register file read 150 ps, register file setup 20 ps, equality comparator 40 ps, AND gate 15 ps.
- Single-cycle, Tc = 925 ps. A
lwgoes through every part in one cycle: 30 + 250 (instruction memory) + 150 (register read) + 25 (mux) + 200 (ALU) + 250 (data memory) + 20 (register file setup) = 925 ps. Every instruction gets this long cycle, even anaddthat never touches the data memory. - Multicycle, Tc = 325 ps. One step per cycle, and the slowest step is a memory access: 30 + 25 (mux) + 250 (memory) + 20 (setup) = 325 ps.
- Pipelined, Tc = 550 ps. The cycle must fit the slowest stage. With the branch decided early in ID, Decode reads the registers, forwards, compares and picks the next PC. The register file is written in the first half of a cycle and read in the second, so the stage counts twice its half: 2 × (150 + 25 + 40 + 15 + 25 + 20) = 550 ps. The other stages need 270–310 ps.
Why the fastest clock loses
The multicycle clock is almost 3 times faster than the single-cycle clock, yet the multicycle processor comes last in every demo. A lw takes 5 × 325 = 1,625 ps instead of 925 ps. Two things go wrong:
- Sequencing overhead. Each cycle pays the register clock-to-Q and setup time (50 ps) again, 5 times for a
lw. - Unbalanced steps. The cycle must fit the memory step (250 ps), so a step that needs less, such as a register read, still takes a full 325 ps.
With CPI between 3 and 5, about 4.1 on a typical mix, multicycle needs about 1,340 ps per instruction. Its real advantage is hardware cost: one memory for instructions and data and one ALU that also increments the PC.
How the pipeline wins: overlap
One instruction takes even longer in the pipeline than in the single-cycle processor: 5 stages × 550 ps = 2,750 ps (its latency). The pipeline wins on throughput: once it is full, one instruction finishes every 550 ps (Demo 2). Ideally CPI is 1; in practice it is a little higher:
cycles = N + 4 (fill) + stall cycles + flushed cycles CPI = cycles / N
- Fill. The first instruction needs 5 cycles to come out; the 4 extra cycles are paid once per program. On 10 instructions they add 0.4 to CPI; on 80 instructions only 0.05 (Demo 6: CPI falls from 1.60 to 1.25, and the lead over single-cycle grows from 1.05× to 1.35×).
- Load-use stall. Forwarding sends an ALU result to the next instruction in time, but a
lwhas its data only at the end of MEM. An instruction that uses the loaded register right away waits 1 cycle in ID, and a bubble goes into EX (Demo 3). - Taken branch. The pipeline predicts that a
beqis not taken and keeps fetching. The branch is decided in ID, so when it is taken, the 1 instruction fetched behind it is flushed (Demo 5). - Branch operands. Because
beqcompares in ID, it needs its registers one stage earlier than an ALU instruction: it stalls 1 cycle after an R-type instruction that computes one of them, and 2 after alw. The preset programs avoid this case.
A compiler can remove load-use stalls by moving independent instructions between a load and its use. Demo 4 runs exactly the instructions of Demo 3, with the five loads first: the 5 stalls disappear and the pipeline goes from second place to first.
The demos side by side
| Demo | Single-cycle | Multicycle | Pipelined | Winner |
|---|---|---|---|---|
| 1 mixed, 10 instructions | 9,250 ps | 42 cycles, CPI 4.20, 13,650 ps | 16 cycles, CPI 1.60, 8,800 ps | pipelined, 1.05× |
| 2 all R-type | 9,250 ps | 40, CPI 4.00, 13,000 ps | 14, CPI 1.40, 7,700 ps | pipelined, 1.20× |
| 3 load-use | 9,250 ps | 45, CPI 4.50, 14,625 ps | 19, CPI 1.90, 10,450 ps | single-cycle |
| 4 loads reordered | 9,250 ps | 45, CPI 4.50, 14,625 ps | 14, CPI 1.40, 7,700 ps | pipelined, 1.20× |
| 5 branch loop | 9,250 ps | 35, CPI 3.50, 11,375 ps | 17, CPI 1.70, 9,350 ps | single-cycle, by 100 ps |
| 6 mixed × 8, 80 instructions | 74,000 ps | 336, CPI 4.20, 109,200 ps | 100, CPI 1.25, 55,000 ps | pipelined, 1.35× |
On short programs full of stalls or taken branches, the single-cycle processor can win: its CPI is exactly 1, and the pipeline's CPI × 550 ps is then more than 925 ps. The repeat select runs any program 2, 4 or 8 times to see how the gap changes as the fill cost spreads out.
The book's numbers: SPECINT2000
Harris compares the three processors on a program of 100 billion instructions with the SPECINT2000 mix: 25% loads, 10% stores, 11% branches, 2% jumps, 52% R-type.
| Processor | CPI | Tc | Execution time |
|---|---|---|---|
| Single-cycle | 1 | 925 ps | 1011 × 1 × 925 ps = 92.5 s |
| Multicycle | 0.13 × 3 + 0.62 × 4 + 0.25 × 5 = 4.12 | 325 ps | 1011 × 4.12 × 325 ps = 133.9 s |
| Pipelined | 1.15 | 550 ps | 1011 × 1.15 × 550 ps = 63.3 s |
The pipelined CPI assumes that 40% of loads are followed at once by a use (CPI of a load 1.4), that 25% of branches are mispredicted (CPI of a branch 1.25) and that a jump flushes one instruction (CPI 2): 0.25 × 1.4 + 0.10 × 1 + 0.11 × 1.25 + 0.02 × 2 + 0.52 × 1 = 1.15. The pipeline is 92.5 / 63.3 = 1.46 times faster than single-cycle, not 5 times: the stages are not balanced (550 ps against 270–310 for the others), each stage adds register overhead, and stalls and flushes raise CPI. On this long program the 4 fill cycles do not matter at all.
See also The Single-Cycle MIPS Processor for one instruction per clock with every control signal, How a Program Runs on the MIPS Datapath for the multicycle steps, and The MIPS Pipeline: Hazards and Forwarding for forwarding, stalls and flushes stage by stage. Those two pages use Patterson and Hennessy's numbers (200 ps stages, branch decided in MEM with a 3-cycle penalty), so their cycle counts differ from Harris' model here. Branch Prediction on the MIPS Pipeline shows how predictors cut the flushes that Demo 5 pays for.
What the page leaves out
Jumps, addi and the other instructions; the branch delay slot of real MIPS; caches and memory stalls (every memory access takes 250 ps here, see CPU caches); the extra hardware and power each design needs; deeper pipelines, superscalar and out-of-order processors, which push CPI below 1 (see Superscalar and Out-of-Order Execution); and the multicycle design's finite state machine that sequences the steps.