The idea: keep what the eye sees, drop the rest
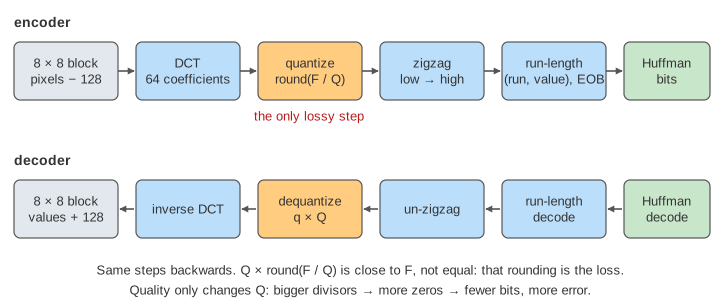
A JPEG photo is cut into 8 × 8 blocks of pixels, and each block is compressed on its own. The trick is to stop describing a block pixel by pixel. Instead JPEG says how much of each of 64 fixed patterns, from flat to finely striped, the block contains. Real images are mostly smooth, so a few coarse patterns carry almost everything, and the fine ones can be stored roughly or not at all.
The DCT: 64 cosine patterns
First 128 is subtracted from every pixel, so the values sit around 0. Then the 2D discrete cosine transform (DCT) gives 64 coefficients:
F(u,v) = ¼·C(u)·C(v)·Σx Σy (p(x,y) − 128)·cos((2x+1)uπ/16)·cos((2y+1)vπ/16)
C(0) = 1/√2,  C(k) = 1 otherwise;  u, v, x, y = 0 … 7
F(u,v) is how strongly the block matches the pattern with u half-waves across and v half-waves down. F(0,0) is the DC coefficient: the flat pattern, equal to 8 × the average. The other 63 are AC coefficients. For the face detail, DC = −415: the block is darker than mid-grey. (Demo 1)
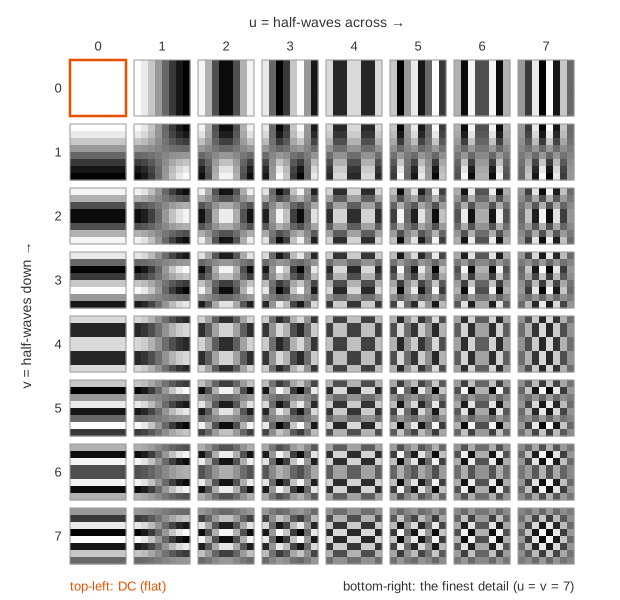
The DCT loses nothing: the inverse DCT adds the 64 weighted patterns back up and gives the pixels exactly. What it does is energy compaction. For the face detail the 6 largest coefficients hold over 90% of the energy (the sum of squares), and the smooth gradient is almost all DC plus two coarse ramps. (Demo 4) It is a cousin of the Fourier transform that uses only cosines, which avoids a jump at the block's edges; see Fourier Series and the FFT and Fourier Series, Harmonic by Harmonic. Fast DCTs use the same butterfly idea as the FFT.
Quantization: the lossy step
Each coefficient is divided by its entry in a quantization table Q and rounded: q = round(F / Q). The table in the JPEG standard (Annex K) has small divisors top-left (16, 11, 10, …) and large ones bottom-right (up to 121), because the eye is far less sensitive to fine detail than to coarse shading. Small high-frequency coefficients round to 0. The decoder can only get back q × Q, so for the DC of the face detail −415.4 / 16 = −25.96 → −26 → −416.
The quality setting (1–100) of libjpeg scales the whole table:
| quality | scale | Q(0,0) | largest Q | face detail: non-zero |
|---|---|---|---|---|
| 90 | 200 − 2·90 = 20% | 3 | 24 | 29 of 64 |
| 75 | 50% | 8 | 61 | 24 |
| 50 | 100% (the standard table) | 16 | 121 | 20 |
| 25 | 5000 / 25 = 200% | 32 | 242 | 12 |
| 10 | 500% | 80 | 255 (the cap) | 7 |
Zigzag and run-length
The 64 quantized numbers are read in zigzag order: (0,0), (1,0), (0,1), (0,2), (1,1), … along the anti-diagonals, from low to high frequencies. The non-zero values come early and the zeros pile up at the end.
Run-length coding then writes each non-zero AC value as a pair (zeros skipped, value). A run of 16 zeros that is not the tail is written as ZRL, and one EOB (end of block) replaces all the trailing zeros. The face detail at quality 50 becomes 21 tokens:
DC −26  (0,−3) (1,−3) (0,−2) (0,−6) (0,2) (0,−4) (0,1) (0,−3) (0,1) (0,1)
(0,5) (0,1) (0,2) (0,−1) (0,1) (0,−1) (0,2) (5,−1) (0,−1)  EOB
Huffman: tokens to bits
Each AC token is stored as a Huffman code for the symbol (run, size), where size is how many bits the value needs, followed by those bits. Common symbols get short codes: (0, size 1) is 2 bits + 1, EOB is 4 bits. The DC is stored as the difference from the previous block's DC, since neighbouring blocks have similar averages; the page encodes the first block, so the difference is from 0. With the standard tables the face detail takes 93 bits instead of 64 × 8 = 512: 5.5 : 1. See Huffman Coding for how such codes are built.
Quality vs size
Lower quality means larger divisors, more zeros, shorter streams and a larger error. The busier the block, the more it costs. (Demos 1–3)
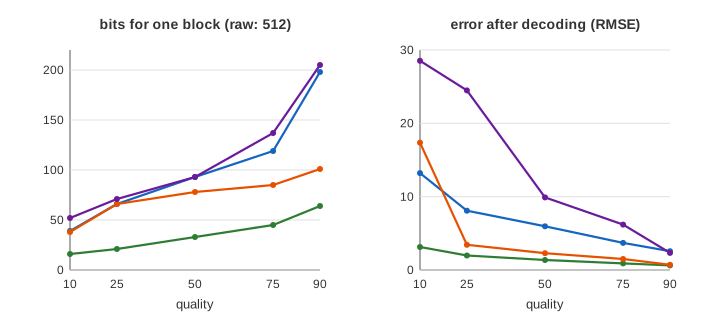
| block | quality 50: bits | RMSE | what goes wrong at quality 10 |
|---|---|---|---|
| smooth gradient | 33 | 1.37 | almost nothing (RMSE 3.1) |
| face detail | 93 | 5.96 | blocking: the block turns into a few soft blobs |
| sharp edge | 78 | 2.29 | ringing: ripples next to the edge, error up to 30 (Demo 5) |
| fine checkerboard | 93 | 9.90 | the texture is gone: one coefficient survives (Demo 6) |
Blocking happens because each block is rounded on its own, so neighbouring blocks no longer meet smoothly. Ringing is the same overshoot as the Gibbs phenomenon in a Fourier series: an edge needs many high frequencies, and quantization cuts them off.
What the page leaves out
Colour: real JPEG converts RGB to Y (brightness) and Cb, Cr (colour), usually stores the colour at half resolution (4:2:0 chroma subsampling) and has a second, coarser table for it. The page shows one luminance block; a real image has thousands, with the DC coded as differences between them. It counts bits with the standard Huffman tables but does not show the codes, the file headers or optimised tables. Progressive JPEG, arithmetic coding, the fast integer DCT, padding of edge blocks, deblocking filters and newer formats (JPEG 2000 wavelets, WebP, AVIF) are not shown.