The idea: ask the time, and time the asking
A computer's clock is a quartz crystal and a counter. It drifts by seconds a week, and after a reboot it can be minutes off. NTP (the Network Time Protocol) fixes it by asking a server that knows the time. The catch: the answer is already old when it arrives, and nobody knows exactly how old. NTP's trick is to time the question too. One request and one reply carry four timestamps, and those four numbers are enough to work out both how wrong the clock is and how long the trip took.
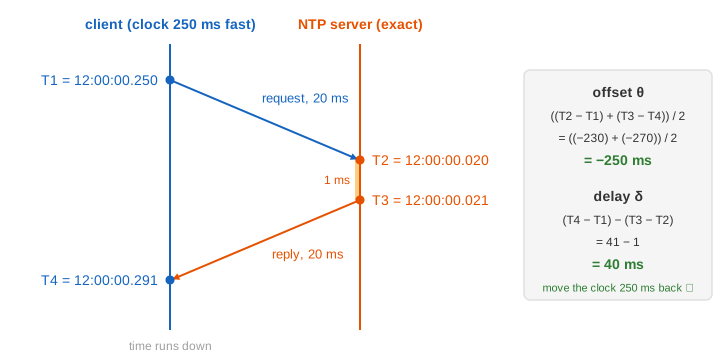
The four timestamps
| name | who stamps it | when | on which clock |
|---|---|---|---|
| T1 (origin) | client | the request leaves | client's (wrong) clock |
| T2 (receive) | server | the request arrives | server's clock |
| T3 (transmit) | server | the reply leaves | server's clock |
| T4 (destination) | client | the reply arrives | client's clock |
The request is a 48-byte UDP packet to port 123 (mode 3, client); the reply (mode 4, server) copies T1 back and adds T2 and T3. The client notes T4 itself. On the page each timestamp flies into its box as it is taken.
Offset and delay
Say the client's clock reads true time + e, the request takes d_out and the reply d_back. Then
T2 − T1 = d_out − e         (the trip out, as seen across two clocks)
T3 − T4 = −d_back − e       (the trip back, the same way)

offset θ = ((T2 − T1) + (T3 − T4)) / 2 = (d_out − d_back)/2 − e
delay  δ = (T4 − T1) − (T3 − T2)       = d_out + d_back
The delay δ is the round trip measured on the client's clock, minus the time the server held the packet; the client's error e cancels because T1 and T4 are on the same clock. The offset θ is how much to move the client's clock. When the trip out and the trip back take the same time, the two delays cancel and θ = −e exactly: the client finds its error to the millisecond (Demo 1). A slow network does not change that, as long as it is slow both ways (Demo 4: 200 ms each way, δ = 400 ms, θ still −250 ms).
The one thing NTP cannot see: an uneven path
The client only knows the sum d_out + d_back, never the two parts. So NTP assumes they are equal, and if they are not, θ is off by (d_out − d_back) / 2. No exchange of messages can detect this: a one-way trip can only be timed by two clocks that already agree, which is what we were trying to get.
| d_out | d_back | δ | θ (true answer −250 ms) | error left |
|---|---|---|---|---|
| 20 ms | 20 ms | 40 ms | −250 ms | 0 |
| 200 ms | 200 ms | 400 ms | −250 ms | 0 |
| 20 ms | 80 ms | 100 ms | −280 ms | −30 ms (Demo 5) |
| 80 ms | 20 ms | 100 ms | −220 ms | +30 ms |
The error is at most half the round trip, so a short δ also means a small worst-case error. That is why nearby servers give better time, and why the next idea works.
The clock filter: trust the fastest sample
ntpd does not act on one exchange. It polls the server again and again (every 64 s at first, stretching to 1024 s when the clock is stable) and keeps the last 8 samples. Queues in routers make some trips slow, and a slow trip usually means one direction waited longer than the other. So the clock filter picks the sample with the smallest delay: it had the least room for queueing. In Demo 6 four polls on a jittery path give δ = 110, 80, 42 and 180 ms; the 42 ms sample (20 ms out, 22 ms back) wins and leaves only −1 ms of error, where the first sample alone would have left −35 ms.
Step, slew and panic
Once it has an offset, ntpd has to move the clock without breaking programs that read it:
| |θ| | what ntpd does | on the page |
|---|---|---|
| ≤ 128 ms | slew: adjtimex() runs the clock up to 500 ppm (0.5 ms per second) fast or slow until the error is gone; time never jumps or goes backwards | Demo 3: 40 ms takes 80 s |
| 128 ms … 1000 s | step: settimeofday() jumps the clock at once, backwards if it was fast | Demo 2: −250 ms, Demo 8: +300 ms |
| > 1000 s | panic: "time correction exceeds sanity limit", ntpd exits and leaves the clock alone (unless started with -g, which allows one big first step) | Demo 7: 2000 s |
A step backwards is why logs can show events out of order and why code that measures durations should use a monotonic clock (CLOCK_MONOTONIC, System.nanoTime()) and not the wall clock. Many servers are set to only slew after boot for this reason.
Stratum: where the time comes from
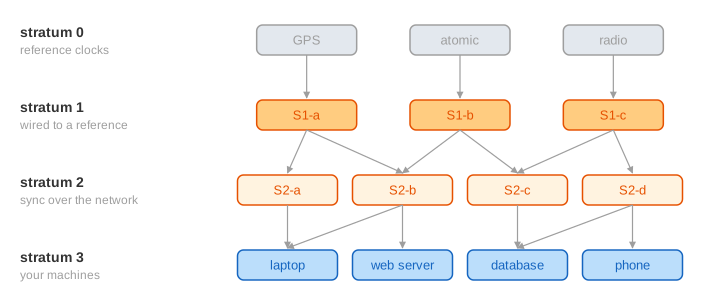
The server on the page is not magic either: it got its time the same way. NTP servers form a hierarchy. A
stratum 1 server is wired to a reference clock (stratum 0: a GPS receiver, a radio clock or an
atomic clock). Stratum 2 servers sync from stratum 1 over the network, stratum 3 from stratum 2, and so on up to
15. Each hop adds a little error, so clients pick the lowest stratum they can reach with a short delay. The
public pool.ntp.org hands out volunteer servers near you by DNS.
See also
When machines cannot trust their wall clocks at all, distributed systems order events with counters instead: see Lamport Clocks. Another small UDP request and reply, with caching and a hierarchy of servers, is DNS Resolution.
What the page leaves out
The client's clock here has a fixed error; a real one also runs at the wrong rate, and ntpd's PLL/FLL loop learns that frequency error (the drift file) so it needs fewer corrections. Real clients ask several servers and use selection and clustering (Marzullo's algorithm) to throw out wrong ones. Also left out: leap seconds, NTS (Network Time Security) authentication, SNTP's simpler client, chrony's different rules, PTP and hardware timestamps (sub-microsecond time in data centres), lost packets and retries, and the 64-bit NTP timestamp format (seconds since 1900).