The idea: a word is known by the company it keeps
word2vec (Mikolov et al., 2013) gives every word a short vector of numbers, an embedding, so that words used in the same places get similar vectors. It never reads a dictionary. It only plays one guessing game over and over: given a word, is this other word one of its neighbours or a random word? The variant on this page is skip-gram with negative sampling (SGNS), the one most people mean by word2vec.
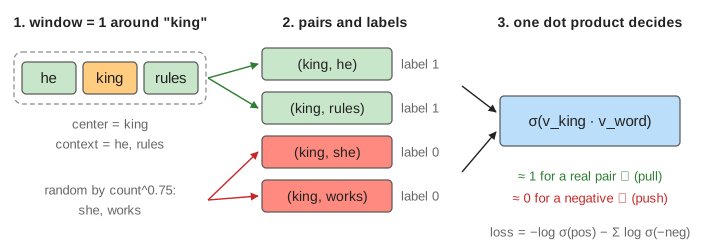
The canvas trains real vectors with only 2 numbers each, so every word is a dot you can watch move. The
corpus is 4 tiny sentences with the stop words already removed: he king rules,
she queen rules, he man works, she woman works.
Context windows and training pairs
The context window slides over the text. The word in the middle is the
center; every word within window positions of it is a
context word, and each (center, context) is one positive pair. With
window = 1 the sentence he king rules gives (he, king), (king, he), (king, rules)
and (rules, king). The 4 sentences give 16 pairs per pass, an epoch. "he" and "rules"
never share a window, so they never form a pair. (Demo: context windows)
Real word2vec uses window = 5 and picks a random smaller window for each center, so close
neighbours are counted more often than far ones.
One training step: pull the real pair, push the negatives
For a pair (c, o) the model's guess is σ(v_c · v_o), the sigmoid of the dot product of the
two vectors: near 1 means "these are neighbours". Alone, the easiest way to say 1 to every pair is to make
all vectors huge and parallel. So each real pair comes with k negative
samples: random words that should get σ ≈ 0. The loss for one pair is
loss = −log σ(v_c · v_o) − Σ over negatives n of log σ(−v_c · v_n)
Its gradient gives the update. For each target word t with label 1 (context) or 0 (negative):
g   = (label − σ(v_c · v_t)) · lr
v_t = v_t + g · v_c
v_c = v_c + Σ g · v_t
For the real pair g is positive, so each vector moves a bit in the direction of the other
and their dot product grows: a pull. For a negative g is negative and the
vectors turn away from each other: a push. The step is large when the guess is badly
wrong and almost zero once σ is right, so pairs the model already knows stop changing.
(Demo: one training step)
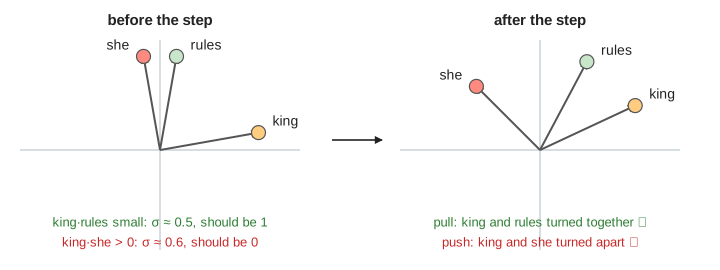
The canvas shows the pull and then the push as two moves. word2vec computes them from the same old
vectors, and so does the page, so the two moves add up to one ordinary SGD step. The learning rate starts
at 0.3 and decays, lr = 0.3 / (1 + epoch / 5); word2vec starts at alpha = 0.025
and lowers it linearly to almost 0.
Why negative sampling
The negatives are drawn from the word counts raised to the power 0.75. Frequent words are drawn more
often, but less than in proportion: a word 16 times as common is drawn 8 times as often. Here "he", "she",
"rules" and "works" appear twice and the four nouns once, so the pronouns and verbs are the usual negatives.
word2vec uses k = 5–20 for small data and 2–5 for big data; the page uses
k = 2.
Without negatives (k = 0) every step is a pull. Every vector keeps turning toward the
others until they all point into the same corner. Then every cosine is high, everything looks similar to
everything and the space carries no information. (Demo: no negatives)
The original alternative is the full softmax over the vocabulary, which needs a sum over every word
(millions) for each pair. Negative sampling replaces it with k + 1 small sigmoids.
Reading the embedding space
After training, words that share neighbours point in similar directions: "king" and "queen" both appear
next to "rules", "king" and "man" both next to "he". In 2D the eight words settle on a ring, each between
the words it shares contexts with. Similarity is measured with the cosine,
cos = v_a · v_b / (|v_a| |v_b|): the angle between the vectors, ignoring their length. A
length mostly tells how often and how consistently a word was trained.
(Demo: train 80 epochs)
The training here uses one vector per word: the center and the context use the same table, so words that appear together are pulled together. Real word2vec keeps two tables, an input vector for a word as a center and an output vector for the same word as a context, and keeps only the input table. Then two words become similar when they have the same neighbours, even if they never appear together.
Analogies are vector offsets
If the vectors have learned that "woman" differs from "man" the same way "queen" differs from "king",
then the offset woman − man is roughly the offset queen − king. So
king − man + woman lands near "queen". The answer is the word with the highest cosine to that
point, leaving out the three input words, which is how the word2vec analogy test scores it.
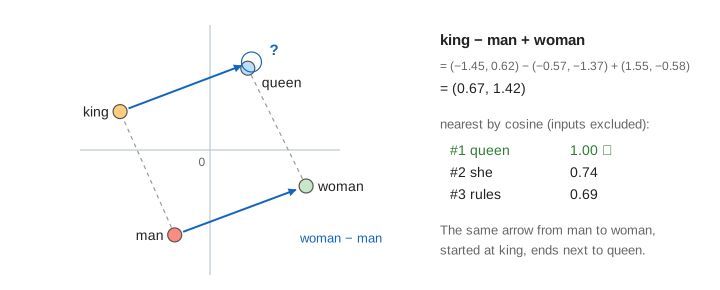
On the canvas, after 80 epochs king − man + woman gives "queen" with cosine 1.00, and the
other two analogies in the menu also come out right. Before training the same arithmetic gives a random
word. (Demos: king − man + woman, analogy before training) On a corpus this small the result
depends on the random start; real embeddings get analogies right from billions of words, and even then only
for some of them (about 60–70% on the original test set with 300 dimensions).
This page vs real word2vec
| Setting | This page | word2vec (Google News vectors) |
|---|---|---|
| corpus | 4 sentences, 12 words | about 100 billion words |
| vocabulary | 8 | 3 million words and phrases |
dimensions (size) | 2 | 300 |
window | 1 | 5 (random 1–5 per center) |
negatives k | 2 | 5–20 |
| vector tables | one (tied) | two: input and output |
| frequent words | removed by hand | subsampled (sample = 1e-5) |
Modern language models still start with an embedding table, but it is learned together with the rest of the network, and its rows are subword tokens rather than whole words: see BPE Tokenizer for where those tokens come from and Self-Attention for how a transformer mixes the embeddings of a sentence, so the same word gets a different vector in each context, which word2vec cannot do. Vectors and the Dot Product explains dot product and cosine, BM25 vs Vector Search shows embeddings used for search, and How a Large Language Model Works shows the embedding table inside a GPT.
What the page leaves out
The second (output) vector table, CBOW (predict the center from the averaged context), hierarchical softmax, subsampling of frequent words, the random shrinking window, the unigram table of 100 million entries that word2vec samples negatives from, phrases such as "New_York", multi-threaded asynchronous SGD, and successors such as GloVe (factorising the co-occurrence matrix) and fastText (vectors for character n-grams, so unseen words get a vector too).